

[For more diverse corporate information on the startups featured in this article, visit the Unicorn Factory big data platform ‘Data Lab’.]
With high-performance artificial intelligence models being released one after another, the cost burden on service operating companies has grown accordingly. Recently launched Anthropic's 'Claude Fable 5.1' and OpenAI's 'GPT-6 Astra' also drew attention for their increased prices, matching their outstanding performance.
The standard API pricing for Anthropic's Claude Fable 5.1 is $10 per million input tokens and $50 per million output tokens. Compared to the company's lightweight model, 'Claude Haiku 4.5' ($1 input, $5 output), it is 10 times more expensive.
As cost gaps widen significantly depending on model performance, a situation has arisen where it is necessary to meticulously examine whether an expensive model truly delivers its worth. Beyond simply selecting high-performance models, the industry's new challenge has become improving AI usage efficiency by comprehensively considering GPU costs, response speed, and actual service outcomes.
Accordingly, analysts point out that the competitive center of gravity in the AI industry is shifting from simple model performance to 'inference efficiency.' Since GPU costs and response latency are directly linked to the profitability of AI services, domestic startups are successively unveiling technologies to lower AI operational costs through various approaches.
Developing 'Inference Efficiency' Technologies to Lower Costs
As more companies build AI models in-house or operate services using external models, GPU costs incurred during the inference process have snowballed. Independent of improving model performance, how much an AI can be run with fewer resources while maintaining the same performance has become a core factor in service operations.
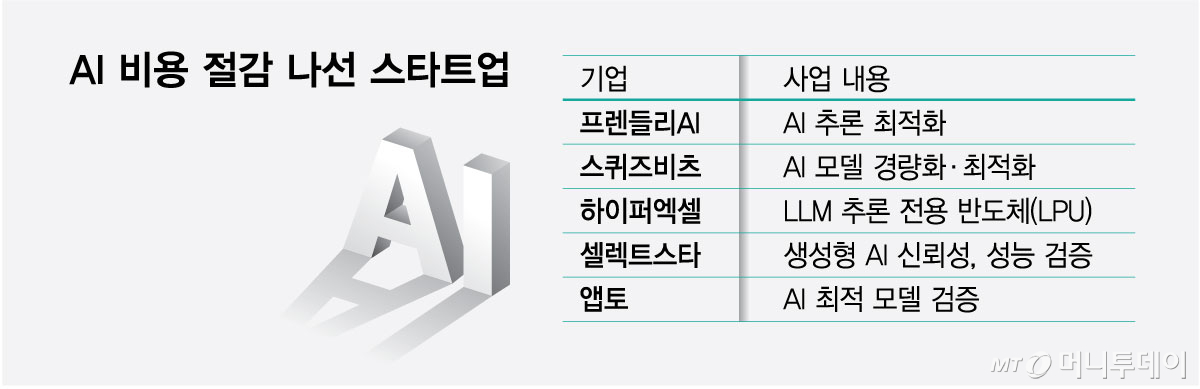
The most direct method is to reduce the infrastructure costs required for running AI models themselves. FriendlyAI provides AI inference optimization technologies, including 'continuous batching.' The core of this technology lies in efficiently bundling requests from multiple users to minimize computation time.
It is explained that by processing more computations on the same GPU infrastructure, GPU costs can be reduced by more than 50%. In fact, Scatterlab, which operates the chatbot service 'Zeta,' is known to have achieved significant infrastructure cost savings by adopting FriendlyAI's technology.
SqueezeBits, established in 2022, developed technology that drastically reduces the memory and computation required for inference while maintaining model performance. After securing investments from Naver D2SF, Kakao Ventures, and Samsung Next, it was acquired by AI semiconductor company Rebellions in June this year. It is interpreted that Rebellions acquired SqueezeBits to secure software capabilities for efficiently running models, in addition to the computational performance of its own AI semiconductors.
Efforts to lower inference costs at the hardware level are also continuing. Hyperaccel, which develops a Large Language Model (LLM) inference-dedicated semiconductor (LPU), focused on maximizing cost efficiency by utilizing memory bandwidth to the extreme while adopting LPDDR instead of expensive High Bandwidth Memory (HBM). It developed a structure that processes computations as much as possible within the core and minimizes data movement, targeting the weakness of LLM inference where the process of repeatedly moving data between memory and computing units becomes a bottleneck.
Companies Digging Into 'Real-World Performance' Validation
The importance of the process itself for deciding which AI model to deploy in a service has also grown. This is because benchmark scores unilaterally disclosed by developers are difficult to use for accurately gauging performance in actual service environments.
AI data and reliability verification company SelectStar has moved to enhance features to address this blind spot in cost efficiency. Currently operating the solution 'DataMo Eval,' which automatically verifies the reliability of generative AI services, SelectStar sets evaluation criteria suited to the service's purpose and generates questions itself to verify the accuracy and safety of answers.
The goal is to add a feature evaluating 'performance per cost' in the first quarter of next year, providing direction for companies to find the optimal AI model that best fits their real-world usage environment.
"Until now, we have mainly focused on evaluating what accuracy is achieved under identical conditions and data," said Kim Se-yeop, CEO of SelectStar. "Going forward, we are updating the platform so that costs can be assessed alongside accuracy and performance by factoring in the time taken for responses and inference costs."
A startup has also emerged that directly compares and verifies a model's service contribution relative to its cost. Apto, established by a Korea University student startup team, targets companies using external LLM APIs. It cross-applies different models to the same AI function and analyzes core behavioral data such as user payments and revisits alongside AI call costs side by side.
Through this, companies can select an 'appropriate model' that drives higher actual revenue and positive user reactions in their own services based on data, rather than relying solely on simple benchmark scores. It is explained that the platform also supports a feature to selectively apply new models to only some users rather than all, allowing for A/B test-like comparisons of performance with existing models, thereby enhancing practical effectiveness.
[MoneyToday Startup Media Platform Unicorn Factory]

 in FUTURE

